 Mentavo
It's half past eleven, and the sentence being typed wouldn't have been said on the phone.
Not because nobody was reachable. Because saying it would have produced a reaction – a face, a follow-up question, possibly concern.
The field on the screen doesn't do that. Which is exactly what makes it easier, and what raises questions that don't come up between people.
Why the threshold is lower
That people disclose things to computer systems they hold back in person has been observed for decades – long before current language models existed.
The explanation is unremarkable: disclosure to people has social consequences. Someone might think differently of you, worry, pass it on, or bring it up next time you meet.
Those consequences are absent when there's no counterpart in the social sense. What remains is the act of putting it into words – without the risk of being judged for it.
Why that can be useful for reflection is covered in the piece on AI as a mirror.
The point of this article is a different one: the social consequence is absent – the technical one isn't.
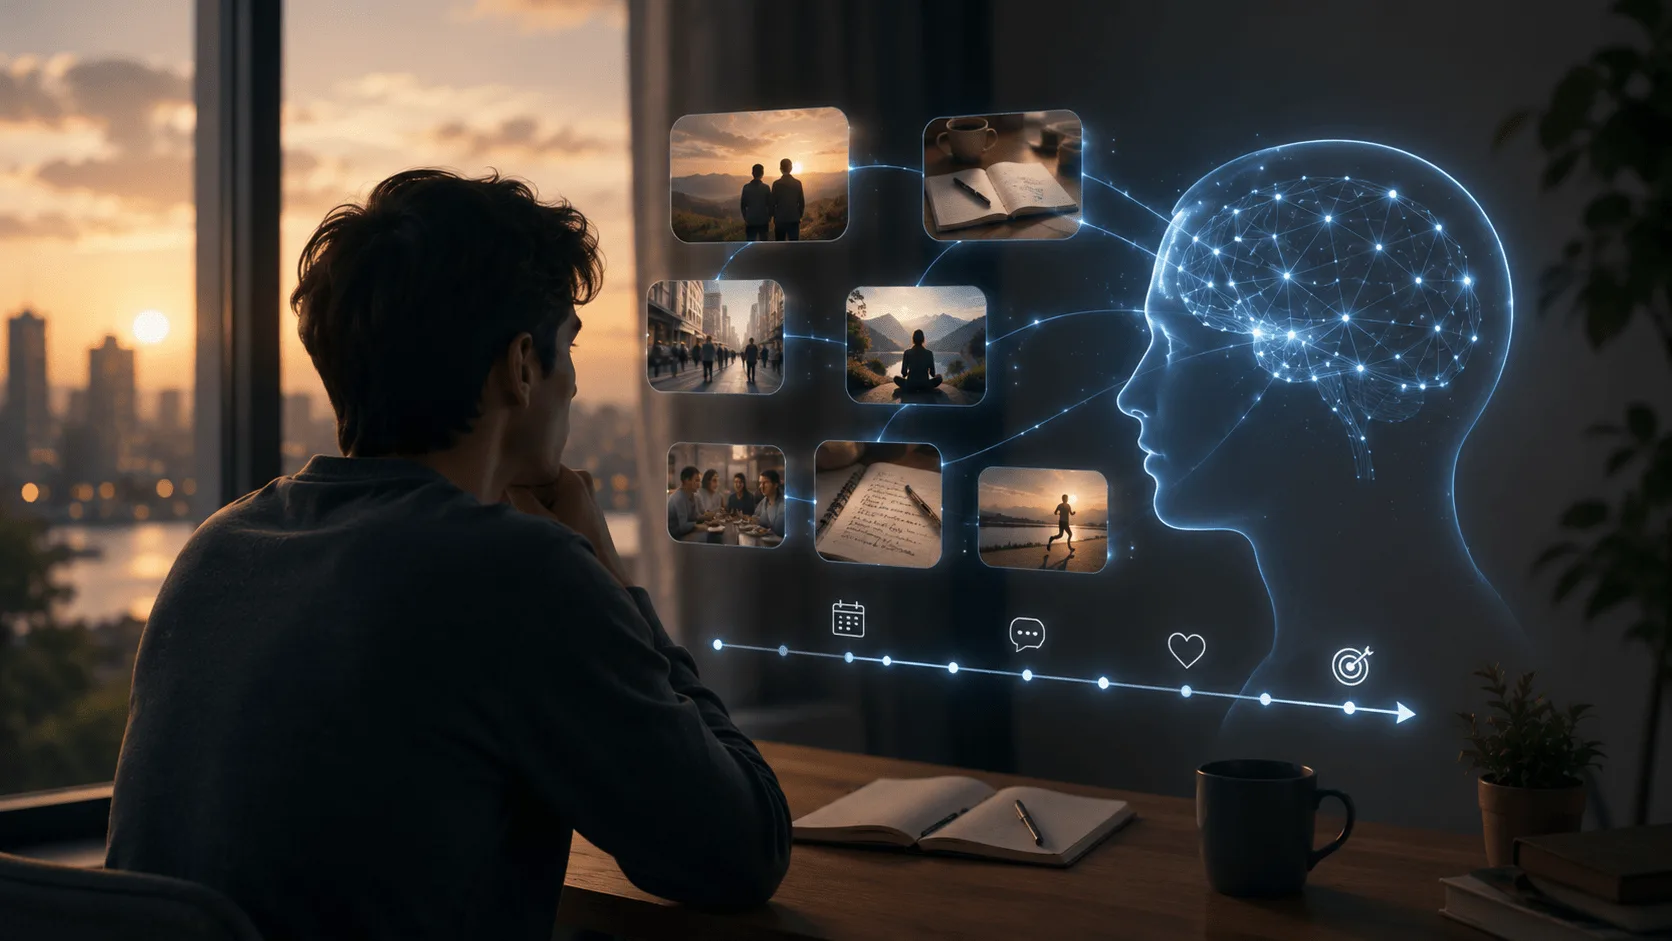
What "remembering" means for software
The word misleads because it's borrowed from human relationships.
When a person remembers, what's remembered fades, shifts and sometimes disappears entirely. When software "remembers", it means something was stored and can be read again under certain conditions. Same word, little in common.
Three questions follow from that, and all of them are more concrete than "is this safe?":
- What is stored? The wording, a summary, or only a note that something took place?
- For how long? Indefinitely, until withdrawn, or with an expiry?
- What can be removed? Individual entries, whole histories, the account – and what then happens to anything derived from them?
The third is the most uncomfortable, because derivations don't always disappear where the original is deleted.
Stored isn't used
A distinction that tends to get lost: storage and use are two separate processes.
Something can be present without being drawn on at a given moment. Conversely, something can be used that was never stored as content in its own right and exists only as a derivation.
For judging the situation that means: "what does the system know about me?" is less useful than "what gets drawn on, and on what occasion?"
| Common question | More useful question |
|---|---|
| Is this safe? | Who has access, and under what conditions? |
| Does it know everything about me? | What is actually drawn on for a single request? |
| Can I delete it? | What exactly gets deleted – and what remains as a derivation? |
| Does it learn from my data? | Does the model learn, or only my own account? |
The privacy paradox
In surveys people consistently express considerable concern about their data. In actual behaviour that concern often plays a smaller part.
This gap between stated attitude and action is described as the privacy paradox. Several explanations exist: the benefit is immediate, the risk abstract and far off. The alternative is frequently going without. And the actual terms are hard to survey.
This finding is itself treated carefully in the research – among other reasons because surveys and observed behaviour don't measure the same thing, and because the decision in a study is usually simpler than the one in daily life.
What follows isn't a reproach to users. It's a reminder that the decision is rarely made deliberately – it gets made in passing the first time, and not revisited afterwards.
What can be settled in advance
Rather than a blanket answer, a short check helps – once, not with every sentence.
The purpose question
What is the recorded material needed for? If a piece of content isn't required for the function, it isn't a necessary price for it either. Data minimisation is less a technical principle than a question you can ask yourself.
The reversibility question
What can be taken back? Deletability says more than any description of security, for one reason: it can be tested.
The worst-case question
Not as an anxiety exercise, but as a measure. What would be uncomfortable if it became visible – and is that content needed for the purpose at all?
For Mentavo, the relevant details are set out in the privacy policy, and the account can be removed via the account deletion page. What's written there is the authoritative version – not this article.
What can't be handed over to technology
There's a part no setting takes care of.
How much of yourself you want to record is a personal decision, not a technical one. It depends on what the record is supposed to be good for – and what would be lost without it.
The same consideration arises in another form with journaling generally: not every thought has to be written down to count. Where the line between reflection and permanent logging runs is covered in when self-reflection turns into self-monitoring.
A second limit concerns the counterpart itself. A system that agrees with everything is pleasant and nearly worthless as a corrective – which is the subject of when AI always agrees.
What this article doesn't claim
It makes no claim about how particular providers handle data – neither approving nor critical. Details like that change and belong in the respective privacy policies.
Nor is it legal advice. Terms such as informational self-determination or data minimisation are used here as aids to thinking, not as legal guidance.
And it neither recommends nor discourages. Being open with a system can be useful; it just isn't a decision that makes itself.
What it would mean for such a memory to run alongside you for years is thought through in the piece on the future of memory.
In short: the threshold is gone, the question isn't
That some things are easier to type than to say isn't a flaw – it's the reason this kind of reflection works at all.
The question isn't whether to be open, but whether you know what happens to what you write and how much of it can be taken back. Both of those answers can be looked up – unlike a feeling of trust.